
Preview
What it is.
You describe a process you already run by hand and it writes the first draft of a skill for it. Then it writes test prompts, runs each one twice, once with the skill loaded and once without, and puts both outputs in front of you.
The second run is what the loop turns on. A skill that reads well can still change nothing about the output, and the pair on one prompt is what shows you that before another afternoon goes into it.
It also tunes the description, which decides whether Claude reaches for the skill at all. It writes 20 trigger queries, splits them 60% train and 40% held-out test, and keeps the description that scores best on the half it held back.
What you get.
- A first draft of the skill, written from a process you describe out loud
- Every test prompt run twice, so the difference the skill makes shows up on the same input
- A browser view with the outputs on one tab and the pass rates and token counts on the other
- A tuned description, scored on the half of the eval set it held back
- A packaged .skill file, when the session can hand you one
How to set it up.
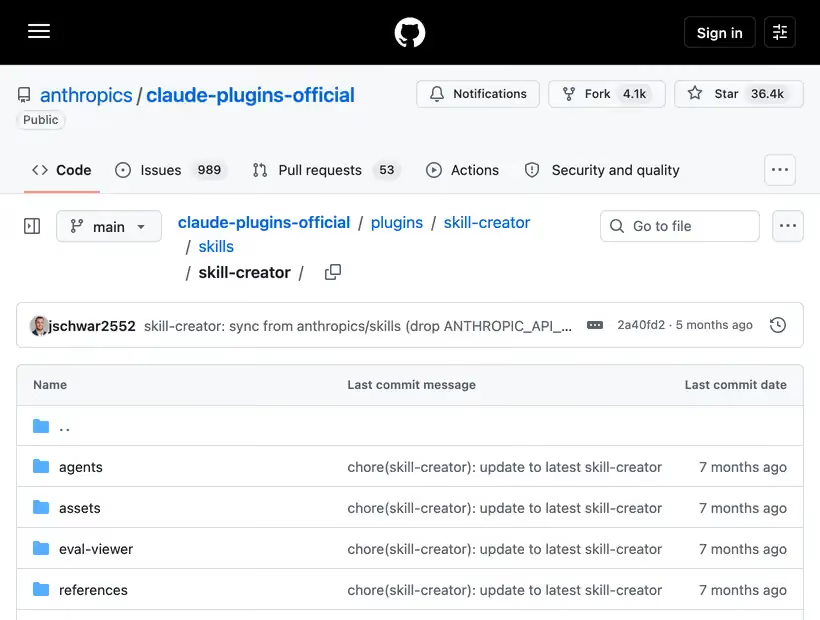
Install it with /plugin install skill-creator@claude-plugins-official. The same skill also sits in Anthropic's example-skills repo if you already have that marketplace added.
Describe a process you already run by hand, including the corrections you usually make afterwards. Those corrections are the part a draft cannot guess.
Approve the 2 or 3 test prompts before anything runs. A vague prompt produces a clean report about nothing.
Let it run each prompt twice, once with the skill and once without. The pair is what shows whether the skill changed the output.
Read the outputs in the browser view it opens and leave feedback per case. An empty box means that one was fine.
Run the description optimizer once the skill settles. It calls the model on every query 3 times across up to 5 iterations, so it is not a step to repeat while the copy is still moving.
Pricing Plans
Free. Apache 2.0 license.
Installs from Anthropic's plugin directory. Nothing to sign up for.
Use cases
The process you explain every time
Somebody asks how you put the monthly report together and you walk them through it again. Describe that walkthrough, including where you usually correct the output, and a draft comes back as a skill you can run.
A skill that reads well and changes nothing
The instructions look right and the output looks the same as before. Running both sides on one prompt shows whether the skill is doing anything, which is the answer you want before rewriting it again.
A skill Claude never picks up
It is written and installed and Claude still passes it over. The optimizer writes trigger queries including near-misses that should stay quiet, then tunes the description against the half of the set it held back.
Two versions and no way to choose
You rewrote a skill and cannot tell whether the new one is better. The blind comparison hands both outputs to an agent that is never told which is which, then reports why the winner won.
Best for
A process you run more than once a month
The loop costs a working session, and a skill you use twice never pays that back.
A skill that already exists and underperforms
It takes the version you came in with as the baseline and measures the rewrite against it.
Anyone whose skill will not trigger
The description is the whole triggering mechanism, and this tunes it against queries you approved first.
A team settling on one way of working
What gets handed over is a folder plus its eval set, so the next person can change it and check what that broke.